Overview¶
How quickly does the chance of a large observation fall as we raise the threshold? The Pareto law models a positive quantity above a lower cutoff. Its tail exponent controls that rate: smaller exponents give more probability to very large observations. Doubling any threshold in its support multiplies the survival probability by .
Basic probability and integration are enough for this page. A survival probability means . The formulas below define the CDF , density , and quantile ; the survival table illustrates the exponent.
Definition and formula summary¶
Let be a positive random variable with lower cutoff and tail exponent . The Pareto Type I distribution is defined by
For , the CDF, density, and quantile function are
The exact Pareto tail is regularly varying with index . Its raw moment of order exists exactly when :
In particular,
and
Thus the mean exists only for , and a finite variance exists only for . Here is the moment order and is the quantile level.
Shape and tail intuition¶
Above its lower cutoff, the Pareto law has no characteristic upper scale. Once both thresholds lie in the Pareto tail, multiplying the threshold by a fixed factor changes the exceedance probability by a fixed power:
Smaller gives a larger exceedance probability at every . The consequences for sums depend on whether the sample size or the exceedance threshold grows; moment existence also depends on the moment order.
The density also shows how the distribution piles mass near the lower cutoff while leaving a long right tail. Its values and scaling make this explicit.
At the cutoff, . For ,
This density exponent differs by one from the survival exponent.
Larger concentrates more mass near and makes the density decay faster. Smaller keeps more visible mass far from the cutoff.
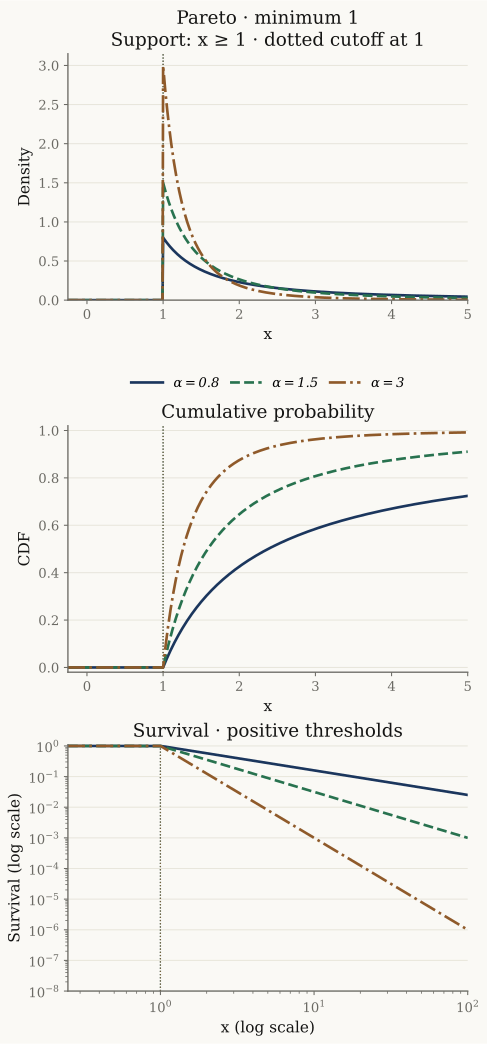
Figure 1:Exact Pareto laws with and . Dotted vertical lines mark the lower support boundary. Larger exponents concentrate more density near 1. For , the log-log survival slope is , while the density exponent is ; below the cutoff, survival is one. The last panel uses positive thresholds and a lower visible probability of 10-8.
The card uses pareto_type1.
Regenerate it with uv run python demos/incerto/distribution_cards.py.
Power-law survival¶
Survival probabilities are usually more revealing than densities for fat-tail work. For an exact Pareto law,
so a log-log survival plot is a straight line with slope :
For , the survival values are powers of the threshold:
| Tail exponent | |||
|---|---|---|---|
| 0.8 | 1 | 2-0.8 | 2-1.6 |
| 1.5 | 1 | 2-1.5 | 2-3 |
| 3 | 1 | 2-3 | 2-6 |
These survival functions trace straight lines on log-log axes because each is an exact power. The heaviest tail has the shallowest line.
The same scaling appears numerically. For a fixed multiplier , the ratio depends only on , provided both and . The identity follows by canceling .
For example, with , doubling any threshold in the support multiplies survival by . This is a direct evaluation of the scaling identity, not an empirical estimate.
Moment thresholds¶
For a positive moment order , the exact Pareto formula is
and the moment is infinite for . The Pareto moment theorem gives the direct integration proof and the truncated-moment formulas and table. Truncation makes each truncated population moment finite: raising the upper cutoff reveals whether it approaches a limit, grows logarithmically at , or grows as a power for .
For a general regularly varying tail, , the boundary depends on . Karamata’s theorem explains this distinction; the exact Pareto boundary always diverges.
The moment-existence thresholds give a concrete example:
With and , the mean is and the second raw moment is infinite; the variance is therefore infinite.
For simulation, inverse transform sampling gives
When is known and the observations are independent and identically distributed exact Pareto draws, the maximum-likelihood estimator is
This formula requires a positive denominator, which holds almost surely under the continuous model. If every observation equals , the likelihood has no finite maximizer; it increases as .
This estimator is not a license to fit an exact Pareto from the sample minimum: empirical tail thresholds are rarely known and must be diagnosed separately.
The symmetric shifted double Pareto model extends the tail construction to signed observations.
Exceedance probability and exceedance size¶
For and , cancellation of Pareto survival probabilities proves the conditional excess law:
This is an exact generalized Pareto survival with shape and scale . It holds at every threshold for this model; no limiting approximation is required. Integrating the nonnegative excess survival gives
Both expectations are infinite for , since the integral of diverges. The first expectation is the mean excess; the second includes the threshold itself. In particular, their ratio to is different.
We also prove the distinction between tail probability and tail contribution to the mean. For any nonnegative and , the pointwise identity and Tonelli’s theorem give
The equality holds in the extended nonnegative reals, including atoms at . For Pareto with it becomes . For , , and , the probability is , the mean excess is 8, the conditional mean is 12, and the tail contribution is . Replacing that contribution by would discard the entire excess integral.
Code
from xmath.incerto.glossary import pareto_tail_quantities

for alpha in (1, 1.5, 3):
    print(f"alpha={alpha:.4g}")
    for name, value in pareto_tail_quantities(alpha, x_m=1, threshold=4).items():
        print(f"  {name}: {value:.4g}")
Output
alpha=1
  log_survival: -1.386
  mean_excess: inf
  conditional_mean: inf
  tail_first_moment: inf
alpha=1.5
  log_survival: -2.079
  mean_excess: 8
  conditional_mean: 12
  tail_first_moment: 1.5
alpha=3
  log_survival: -4.159
  mean_excess: 2
  conditional_mean: 6
  tail_first_moment: 0.09375
These definitions clarify SCoFT v4 §2.2.4, pp. 10–11, and §§2.2.23–24,
pp. 17–18 Taleb, 2025. The exact Pareto calculation here does not
classify arbitrary tails from a finite mean-excess plot. Reproduce it with
uv run python demos/incerto/glossary_worked_cases.py; the script also reports
the infinite-mean cases without replacing infinity by a finite cutoff.
Why the known-cutoff likelihood formula needs conditions¶
We prove the estimator stated above for iid exact Pareto observations, known , and observed . Let . Terms independent of can be omitted from the log likelihood, leaving
If , the unique maximizer is . If , every observation equals and increases without bound as . Observations below are outside this model’s support. A threshold estimated from the same sample changes the problem; this proof supplies no guarantee for that fit.
Sums and moment orders¶
Let be iid Pareto Type I variables with the same and , and put and . For a growing sample, the max-to-sum ratio has three regimes:
If , then almost surely. The linked finite-mean proof gives and almost surely, so their quotient tends to zero.
If , then , where has a nondegenerate distribution on . In particular, the ratio does not tend to zero in probability, nor does it tend to one. This limit theorem is cited rather than proved here Darling, 1952, Theorem 5.1. Kevei and Mason (2014), p. 632 restate the iid result and give the corresponding sum/maximum limit law; our ratio is its reciprocal.
If , the mean is infinite but in probability. More precisely, is bounded in probability and in probability. The calculation below proves these exact-Pareto assertions; it does not assert almost-sure convergence of the ratio.
For every , a different limit holds when the integer is fixed and the threshold grows:
This is the subexponential rare-event statement: a fixed-size sum exceeds a sufficiently high threshold mainly when one summand exceeds it. It holds even when and the largest share vanishes along growing samples. For moments, the separate exact criterion is if and only if , for , as proved in Pareto Moment Existence.
Exact-Pareto boundary calculation¶
We prove the two normalizations used above for . For and sufficiently large , independence gives
For the sum, write and, for , set and . Integration of the density on gives and . Hence
The normalized expectation tends to 1. Chebyshev’s inequality gives convergence in probability for the truncated sum. The union bound transfers that convergence to . Dividing the tight normalized maximum by this normalized sum and by proves in probability.
Fixed-size rare-event calculation¶
We extend the two-summand bound on the subexponentiality page to prove the displayed fixed- result. The case is immediate. For fixed , choose with . If but , either one observation lies in , or at least two observations exceed . Otherwise the sum is at most . Thus
After division by , the first bracket tends to zero because ; the second tail ratio is . Finally, . Nonnegativity makes a subset of , and the negligible residual probability proves the sum-tail equivalence.
Positive sums and independent products¶
The sum and product discussions in SCoFT v4 §§5.2.1–5.2.2, pp. 98–100 Taleb, 2025, require different assumptions. Here we prove a bounded claim about sums and exact formulas for independent Pareto products.
Fix , positive weights , and nonnegative with eventually, where and each is slowly varying. Dependence is unrestricted. For ,
The lower bound uses nonnegativity; the upper bound holds because a sum above has some term above . Put . The logarithmic regular-variation consequence makes both bounds , so . These bounds establish a logarithmic exponent, not a limiting survival constant or full regular variation of every dependent sum. If one allows signed variables, take a symmetric power-tailed and : both have right power tails but their sum is identically zero.
For products, let be independent unit-cutoff Pareto variables with exponents . The symbols are local exponents in this two-law calculation. For , condition on to obtain
For unequal exponents the smaller one determines the leading power. Equal exponents introduce a logarithmic factor, which is slowly varying but never constant. With , , the survival is ; with , it is . For other Pareto minima, apply the formula to .
Independence cannot be suppressed: gives the square, with exponent . Multiplication by a dependent bounded variable can even remove the tail: gives product one. Claims that multiplication always preserves the heavier tail therefore need additional hypotheses. The power-transformation proof handles deterministic powers separately.
Use pareto_product_logsf.
import numpy as np
from xmath.incerto.power_laws import pareto_product_logsf

for a, b in ((1, 2), (1, 1)):
    survival = np.exp(pareto_product_logsf(np.log([1, 10, 100]), a, b))
    print(f"a={a:d}, b={b:d}: [" + ", ".join(f"{v:.4g}" for v in survival) + "]")
Output
a=1, b=2: [1, 0.19, 0.0199]
a=1, b=1: [1, 0.3303, 0.05605]
Equal exponents introduce the logarithmic factor derived above.
Figure regeneration: uv run python demos/incerto/power_laws.py for these product survivals,
the moment-integral figure,
and exact population checks. This adds no new growing-sample dominance claim;
the earlier three max-to-sum regimes remain unchanged.
Caveats¶
Empirical data rarely follows an exact Pareto law from its minimum value. A tail model needs a threshold choice, diagnostic plots, and sensitivity checks.
A finite theoretical mean can still be practically hard to estimate when is close to 1. The issue is pre-asymptotic behavior, not merely the formal existence of .
The exact failure mode depends on the moment order. At , the cutoff moment grows like ; for , it grows like .
Do not estimate high moments of heavy-tailed samples without checking whether those moments are implied by the fitted tail exponent.
A rare Pareto regime retains its power tail¶
The regime question in SCoFT v4 appendix A, §A.1, pp. 122–124 Taleb, 2025, does not by itself specify a Pareto law. Here is an example that does. With probability , draw a Pareto variable with cutoff and exponent ; otherwise draw a uniform variable on . For , conditioning on the regime proves
For every positive order , the mixture moment is . The existing moment proof therefore implies finiteness exactly when . A small positive mixture weight changes the survival constant but not the exponent or moment gate. At the model becomes bounded and all positive moments exist.
With , , , survival at is 0.0025, the mean is 0.55, and the second moment is infinite. These are population values; they do not predict which tail observations will occur in a small sample. The catalog’s normal location mixture has a different tail class even when its regimes are widely separated. The chapter-6 demo prints this example without sampling or clipping it.
References¶
Taleb (2025), §§5.1.1 and 5.2, pp. 95–100: scaling, sums, products and powers. The new finite-sum bounds and product formulas above are proved with explicit support and dependence assumptions.
Darling, “The Influence of the Maximum Term in the Addition of Independent Random Variables,” Transactions of the American Mathematical Society 73 (1952), 95–107, Theorem 5.1 DOI.
Kevei and Mason, “The limit distribution of ratios of jumps and sums of jumps of subordinators,” ALEA 11 (2014), 631–642; p. 632, Theorem 1.1 and the discussion of the iid result PDF.
Embrechts, Klueppelberg, and Mikosch, Modelling Extremal Events 1997.
Resnick, Heavy-Tail Phenomena 2007.
Backlinks¶
Generalizes to: Regular Variation; moment consequences are covered by Karamata’s theorem.
Used by: Double Pareto Distribution, Pareto Moment Existence, Pre-Asymptotic LLN Behavior, Max-to-Sum Ratio, and Hill Estimator.
- Taleb, N. N. (2025). Statistical Consequences of Fat Tails (3rd ed.). https://arxiv.org/abs/2001.10488v4
- Darling, D. A. (1952). The Influence of the Maximum Term in the Addition of Independent Random Variables. Transactions of the American Mathematical Society, 73(1), 95–107. 10.1090/S0002-9947-1952-0048726-0
- Embrechts, P., Klüppelberg, C., & Mikosch, T. (1997). Modelling Extremal Events. Springer. 10.1007/978-3-642-33483-2
- Resnick, S. I. (2007). Heavy-Tail Phenomena: Probabilistic and Statistical Modeling. Springer. 10.1007/978-0-387-45024-7