Main facts¶
The SCoFT Prologue guide separates Gaussian-relative kurtosis from asymptotic tail classes. This catalog compares nonnegative right-tail models by subexponentiality and regular variation, then checks which moments exist. The definitions concern a specified population law.
The positive classifications are cited, not proved here: Foss, Korshunov, and Zachary, second edition (2013), §3.5, Theorem 3.29 and its following paragraph, p. 57 (regular variation, including Pareto); Theorem 3.30 and its following examples, p. 58 (lognormal and Weibull with shape below one). See the book. We derive the elementary tail ratios and moment contrasts below; the appendix proves the convolution decomposition.
Let be the survival function. In the table, “regularly varying” means for some , so for fixed . Here is the CDF, is the threshold, and is a positive tail exponent. All examples below have nonnegative support, with positive scale parameters, positive gamma shape and rate, and nonzero lognormal log-variance. See Shared notation.
| Distribution | Subexponential? | Regularly varying? | Diagnostic tail behavior |
|---|---|---|---|
| Pareto, | Yes | Yes | Exact power tail. |
| Lognormal | Yes | No | Heavier than any exponential, lighter than any power. |
| Weibull, with | Yes | No | Stretched exponential tail. |
| Exponential | No | No | Memoryless light tail. |
| Gamma | No | No | Exponential tail with a polynomial factor. |
For the lognormal row, “heavier than any exponential, lighter than any power” means the survival function satisfies
The inclusion direction to remember is:
for distributions supported on . The converse fails: lognormal and stretched-Weibull tails are subexponential without being regularly varying.
Slow variation need not settle to a constant¶
SCoFT v4 §§2.2.1 and 2.2.11, pp. 9 and 13, discuss a practical transition to a nearly constant tail factor Taleb, 2025. Such a transition is an extra modeling assumption. The definition of slow variation does not imply a finite constant limit, or an exact Pareto tail beyond a finite threshold.
Here is a complete counterexample, in dimensionless units:
We prove that this is a survival function with a regularly varying tail. It is continuous at 1, tends to zero at infinity, and its derivative on is . Thus it defines a probability law on . Its factor tends to infinity, while for every fixed and sufficiently large ,
The chapter 2 worked cases evaluate this ratio alongside the exact Pareto ratio at multiplier 2. A finite curve cannot establish where a tail approximation becomes adequate; threshold selection requires its own diagnostics. The example disproves a constant-limit requirement analytically.
Moment gates are different questions¶
The Cramér condition asks whether for at least one . Ordinary moments ask about , with . For the following nonnegative models:
| Model | Finite positive power moments | Finite positive exponential moments |
|---|---|---|
| Exponential, rate 1 | Every | Exactly |
| Lognormal, | Every | None |
| Pareto Type I, , | Exactly | None |
The Pareto moment proof gives the last row’s power-moment boundary, including divergence at ; the Cramér note proves its exponential-moment failure. For the exponential row, direct integration gives and when ; the latter integral diverges when . Here denotes the gamma integral.
Proof of the lognormal moment contrast¶
We prove both entries in the lognormal row. Let and . Completing the square gives, for every real ,
In contrast, for any fixed ,
Indeed, as , so the integrand is at least 1 for all sufficiently large . The integral over that half-line diverges. This establishes failure of the Cramér condition despite all positive power moments being finite. Subexponentiality is a separate, cited result; it does not follow just from this failure.
For a Pareto model with and , the mean is and the variance is , but the fourth moment diverges. The formulas follow from the linked integral: and . Pearson kurtosis is therefore not a finite summary for this model. Having a finite variance does not imply a finite fourth or positive exponential moment.
Reusable diagnostics¶
For a nonnegative continuous law with unbounded support, compare
where are iid and is fixed. The first ratio checks multiplicative tail scaling; the second is the defining two-summand subexponential ratio. These are population quantities. Finite evaluations of them do not certify an asymptotic class from data.
| Distribution and parameters | Multiplier ratio | Limit of |
|---|---|---|
| Pareto Type I, | 1 | |
| Lognormal, | 1 | |
| Weibull, | 1 | |
| Exponential, rate 1 | ||
| Gamma, shape 2, rate 1 |
Here is the standard normal survival function. For the lognormal row, the normal-tail asymptotic , with the standard normal density, yields
The asymptotic for follows from the complementary-error-function expansion in NIST DLMF, Eq. 7.12.1. It also gives for this standard lognormal as . Adding or proves the two exponential-versus-power comparisons stated above. For with , replace in the normal-tail calculation by ; the same comparisons and zero multiplier-ratio limit follow. Thus the multiplier diagnostic separates power tails from all four other examples, but cannot distinguish subexponential lognormal and stretched-Weibull tails from the two light-tailed examples. The classifications of lognormal and stretched Weibull are cited results; a ratio table is not a proof of their subexponentiality.
Exact light-tail checks¶
We prove the two negative classifications in the table. Write in shape–rate notation, with . At rate one, convolution of the densities with shapes and gives
using the beta integral (NIST DLMF, Eq. 5.12.1). Thus independent shapes add. Scaling by gives the same rule at a common rate . The survival integral, compared with its leading integrand by l’Hôpital’s rule, gives
For completeness, at rate one the derivatives of and have ratio ; both functions tend to zero. Consequently, for fixed ,
This proves that every positive-shape gamma law, including the exponential case , is neither regularly varying with a finite positive exponent nor subexponential.
For integer and rate one, repeated integration by parts gives the exact survival for . Hence
| Threshold | Exponential sum ratio | Gamma shape 2 sum ratio |
|---|---|---|
| 2 | 1.5 | |
| 10 | 5.5 | |
| 100 | 50.5 |
Both ratios diverge, although the gamma ratio happens to be near one at . A single moderate-threshold observation is insufficient to infer a limiting tail class. The Cramér condition provides the exponential-moment contrast for these two light-tailed laws.
A finite model comparison¶
Use pareto_type1, log_survival_multiplier_ratio.
from scipy.stats import expon, lognorm
from xmath.incerto.distributions import pareto_type1
from xmath.incerto.tail_classes import log_survival_multiplier_ratio

for label, law in (("Pareto", pareto_type1(2.5)),
                   ("Lognormal", lognorm(1)), ("Exponential", expon())):
    log_ratio = log_survival_multiplier_ratio(law.logsf, [2, 10, 100])
    print(f"{label}: [" + ", ".join(f"{v:.4g}" for v in log_ratio) + "]")
Output
Pareto: [-1.733, -1.733, -1.733]
Lognormal: [-1.081, -2.052, -3.563]
Exponential: [-2, -10, -100]
A finite grid illustrates the specified laws and cannot classify unknown data.
Figure regeneration: uv run python demos/incerto/prologue_tail_classes.py from the
repository root. It evaluates for Pareto
, standard lognormal, Weibull ,
exponential (rate 1), and gamma (shape 2, rate 1).
The fixed grid has 241 logarithmically spaced thresholds from 1 to 104;
all quantities are dimensionless population calculations. There is no
sampling, data fitting, truncation of a distribution, or uncertainty interval.
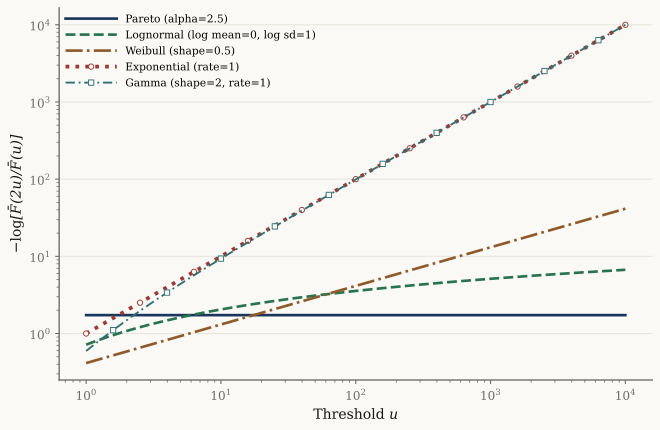
Theoretical survival functions evaluated on a finite grid. The ordinate is : an increasing curve means a decreasing multiplier ratio. The lognormal and stretched-Weibull curves share their zero-ratio limit with the two light-tailed models, although their convolution tails belong to a different class. The exponential curve (brick, circles) and gamma curve (teal, squares) nearly coincide at high thresholds. Their ordinates are and , respectively: the gap tends to while both grow like . Logarithmic axes make that relative gap small. Distinct markers and line widths preserve both curves without shifting their values.
The script also prints exact exponential and gamma two-sum checks at . The helper uses log survival values for the multiplier figure; non-finite values cause an error. In particular, it does not divide zeros when an ordinary survival function underflows. The figure is numerical illustration of the formulas above, not evidence of an observed tail class.
A survival that varies slowly itself¶
The positive-exponent convention in the table does not exhaust regularly varying functions. To examine the index-zero boundary, let be Pareto with minimum , exponent , and dimensionless values, and put . Here are local parameters; the survival exponent of will be zero. This construction is motivated by SCoFT v4 §5.5, pp. 102–103 Taleb, 2025. Inverting the increasing transform proves
For every fixed , its survival ratio tends to one because . Thus , outside this catalog’s positive-power rows. Every positive power moment diverges: , and the exponential factor eventually exceeds every polynomial in the Pareto density integral.
We also prove subexponentiality directly for this example. For iid nonnegative , with ,
Both bounds divided by tend to one: the maximum-tail formula is and . The squeeze proves the claim. Thus a regularly varying survival can be subexponential even when its index is zero. There is no finite positive calibration at this index-zero boundary.
The chapter demo evaluates this survival using with , , obtaining . It keeps the thresholds in logarithmic coordinates to avoid overflowing . Finite evaluations do not stand in for the moment-divergence or convolution proofs.
The maximum-entropy note gives another construction of power tails, conditional on specified information constraints. Neither construction establishes a tail law for observed data.
Regime separation is not a tail class¶
Appendix A of SCoFT v4, §A.1, pp. 122–124 Taleb, 2025, considers distributions with separated regimes. We can check the effect on kurtosis without assuming a power tail. Let take -1 and 1 with equal probabilities, let be independent, and set , with and . Symmetry gives mean zero. Expanding and discarding the odd terms proves
Here is Pearson kurtosis. For it lies below three and tends to one as . Yet for every real . This location mixture is light-tailed. Its density has a local minimum at zero when : differentiating the two normal densities gives . Thus low kurtosis can accompany a valley around the expectation. It is not evidence of a small probability of a large regime change.
For , , the variance is 5 and . The variance-mixture note holds the location fixed and mixes variances; these are different experiments. A finite normal mixture has positive density everywhere, so a valley is not a forbidden interval and every individual point still has probability zero.
An absorbing state needs repeated chances to be reached¶
For the §A.2 context, pp. 124–125, take a homogeneous two-state Markov chain with states intact and failed. The failed state is absorbing and an intact system fails with probability at each step, conditional on still being intact. Its row-stochastic transition matrix is
Induction proves the power: multiplying by multiplies the remaining intact probability by . Starting intact, eventual failure has probability one if and zero if . Irreversibility alone is not sufficient; reachability and persistent conditional risk matter. With varying conditional hazards , intact survival is . For example, has sum , and by induction. Every step has positive risk but eventual failure is not certain. The existing survival calculation treats this product; we do not replace it with an independence assumption on unconditional events.
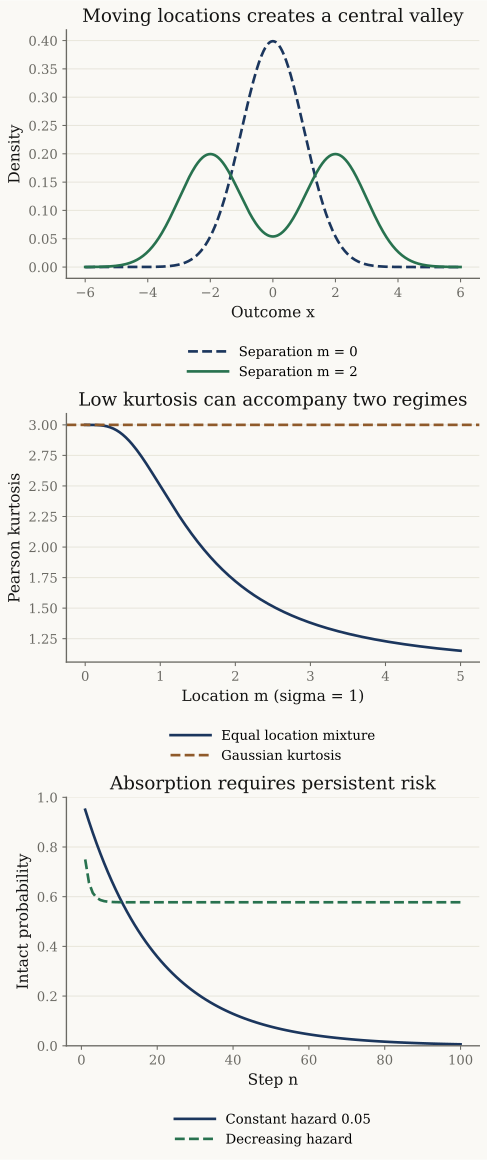
Exact appendix-A examples. The location mixture uses , with
and 2 in the density panel. The last panel compares conditional
hazard 0.05 each step with , starting intact. The first
survival tends to zero; the second stays at least . Neither construction
asserts a power-tail law. Figure regeneration: uv run python demos/incerto/multivariate_tails.py.
Use normal_location_mixture_kurtosis, survival_from_hazards.
from xmath.incerto.multivariate import normal_location_mixture_kurtosis
from xmath.incerto.lecture_risk import survival_from_hazards

print(f"Location-mixture kurtosis: {normal_location_mixture_kurtosis(2):.4g}")
print(f"Constant hazard: {survival_from_hazards([0.05] * 100)[-1]:.4g}")
hazards = [2.0**(-j - 1) for j in range(1, 101)]
print(f"Decreasing hazard: {survival_from_hazards(hazards)[-1]:.4g}")
Output
Location-mixture kurtosis: 1.72
Constant hazard: 0.005921
Decreasing hazard: 0.5776
Neither example asserts a power-tail law.
The Pareto mixture contrast shows what changes when one regime actually has a power tail.
Caveats¶
Regular variation and subexponentiality concern limits, not the shape of a fitted curve on a finite range.
Very small survival probabilities can underflow in numerical calculations. Logarithmic ratios help preserve information; rounded zeros do not establish exact zero probability.
The subexponential definition used here is the right-tail iid version for nonnegative summands. Two-sided and dependent settings need additional assumptions.
The finite exact examples above check formulas, not the accuracy of an upstream sampler, survival-function implementation, or quadrature routine.
Appendix: convolution calculation¶
This appendix proves the elementary two-summand convolution decomposition used by the subexponential diagnostic. We work with independent continuous variables, then specialize to an iid lower-bounded distribution. Discrete, dependent, and two-sided variants require separate assumptions.
For independent continuous random variables and with densities , and survival functions , ,
To see the iid reduction, take a common density , survival function , and lower support endpoint , with . Split the event into three cases, ignoring probability-zero boundary points: first , second , and third both variables exceed . In the first case, conditioning on with leaves the requirement , so this part contributes . The second case contributes the same quantity by iid symmetry. The remaining upper-right square has probability by independence.
For , the partition can be recorded as disjoint regions rather than a contour plot. Boundaries have zero probability under the continuous-law assumption.
| Region within | Probability contribution |
|---|---|
| , | |
| , | The same integral by iid symmetry |
| , |
For iid variables with lower support endpoint , symmetry gives the more useful half-line formula
Dividing by yields a normalized integral:
The logarithmic form applies where the factors are positive, with zero terms understood by limits. It avoids forming tiny unnormalized probabilities before taking their ratio. The decomposition is an ordinary conditioning argument; no numerical integration or executable package helper is needed for it.
References¶
Taleb (2025), appendix A, §A.1, pp. 122–124, and §A.2, pp. 124–125: regime-mixture and transition context. The symmetric-location and absorbing-chain special cases are proved above.
Taleb (2025), §5.0.1, pp. 91–93, and §5.5, pp. 102–103: classification and log-Pareto context. The new index-zero calculation is proved here; earlier positive classifications retain the references below.
Bingham et al. (1987), Regular Variation.
Embrechts, Klueppelberg, and Mikosch, Modelling Extremal Events 1997.
Foss, Korshunov, and Zachary, An Introduction to Heavy-Tailed and Subexponential Distributions 2013, 2nd ed., §3.5, Theorem 3.29 and following paragraph, p. 57; Theorem 3.30 and following examples, p. 58. These support the cited positive classifications.
Taleb, Statistical Consequences of Fat Tails, third edition (2025), arXiv:2001.10488v4, ch. 1, terminology discussion, pp. 4–5: context for the companion Prologue guide, not a theorem source for this table.
Backlinks¶
Depends on: Subexponentiality and Regular Variation.
Example distribution: Pareto Distribution.
Related diagnostic: Max-to-Sum Ratio.
- Foss, S., Korshunov, D., & Zachary, S. (2013). An Introduction to Heavy-Tailed and Subexponential Distributions (2nd ed.). Springer. 10.1007/978-1-4614-7101-1
- Taleb, N. N. (2025). Statistical Consequences of Fat Tails (3rd ed.). https://arxiv.org/abs/2001.10488v4
- Bingham, N. H., Goldie, C. M., & Teugels, J. L. (1987). Regular Variation. Cambridge University Press. 10.1017/CBO9780511721434
- Embrechts, P., Klüppelberg, C., & Mikosch, T. (1997). Modelling Extremal Events. Springer. 10.1007/978-3-642-33483-2