Statement¶
For realized nonnegative observations with , define
The realized max-to-sum ratio is the share of the total produced by the largest observed value. Its random-sample counterpart is , where and . When are iid nonnegative variables with finite positive mean , then
Thus a persistent large realized value is a warning sign that the sample sum is being governed by extremes rather than by aggregation. For Pareto Type I samples with , the ordinary mean is infinite, so the finite-mean argument below does not apply.
Lowercase symbols describe the observed list; uppercase symbols describe random samples. For a nonnegative list with positive total, . If the total is zero, the ratio is undefined. For the almost-sure limit, ensures that eventually almost surely; any convention on earlier zero totals gives the same limit.
Extreme-dominance intuition¶
In a thin-tailed or comfortable finite-mean sample, the largest observation may be memorable, but it should eventually become a negligible fraction of the whole. The total grows like , while the largest draw grows more slowly than on the scale needed to dominate the sum.
Fat-tailed samples can look different. One observation can represent a large fraction of all observed mass, especially near or below the Pareto mean boundary . This is the same mechanism behind LLN Failure Under Infinite Mean, but makes the dominance visible without plotting the entire running average. It complements the path view in Pre-Asymptotic LLN Behavior.
Finite-mean proof¶
We prove the finite-mean theorem: if the iid nonnegative observations have a positive finite mean, then the maximum becomes a negligible share of the sum. The proof uses the strong law and Borel--Cantelli. The infinite-mean Pareto regimes are cited or described heuristically, because their exact limits need heavier regular-variation machinery.
Assume are iid and . The strong law gives almost surely. It remains to show that almost surely.
For any , integrability implies
because the sum is bounded by a constant multiple of . By Borel--Cantelli, almost surely. Therefore almost surely: after a random finite index all new observations are at most , while the finitely many old observations divided by vanish. Hence
almost surely.
For a Pareto Type I tail, Pareto Moment Existence shows that the mean exists exactly when . The regimes are qualitatively different:
: almost surely by the finite-mean theorem.
Exact Pareto : in probability, but slowly; is bounded in probability, while in probability (a cited limit). This is not almost-sure convergence of the ratio.
: under standard regular-variation assumptions, has a nondegenerate limiting distribution Darling, 1952. Infinite mean does not imply that one observation asymptotically equals the whole sum; several of the largest observations may keep material shares.
For iid nonnegative variables with , the converse to the finite-mean theorem also holds: almost surely if and only if . This converse is cited from O'Brien (1980), not proved above. It does not rule out convergence in probability with an infinite mean, as the exact Pareto case shows.
An exact running-list diagnostic¶
Consider the illustrative list . No distribution is fitted to these numbers; they isolate the effect of a record observation.
| Prefix length | Total | Maximum | Largest share |
|---|---|---|---|
| 4 | 4 | 1 | |
| 5 | 20 | 16 | |
| 9 | 24 | 16 |
Adding the record changes the largest share abruptly. Later small observations increase the denominator while leaving the maximum fixed. Reordering the list changes this path but preserves the final ratio.
For an exact Pareto law with , the Frechet maximum scale is , whereas the sum is asymptotic to . Thus a typical ratio has scale : its exponent is at and at . This scale comparison supplies no universal finite- quantile or confidence bound. The infinite-mean limits cited above require separate asymptotic results; the simulation below illustrates finite samples.
Paths and repeated samples across the mean boundary¶
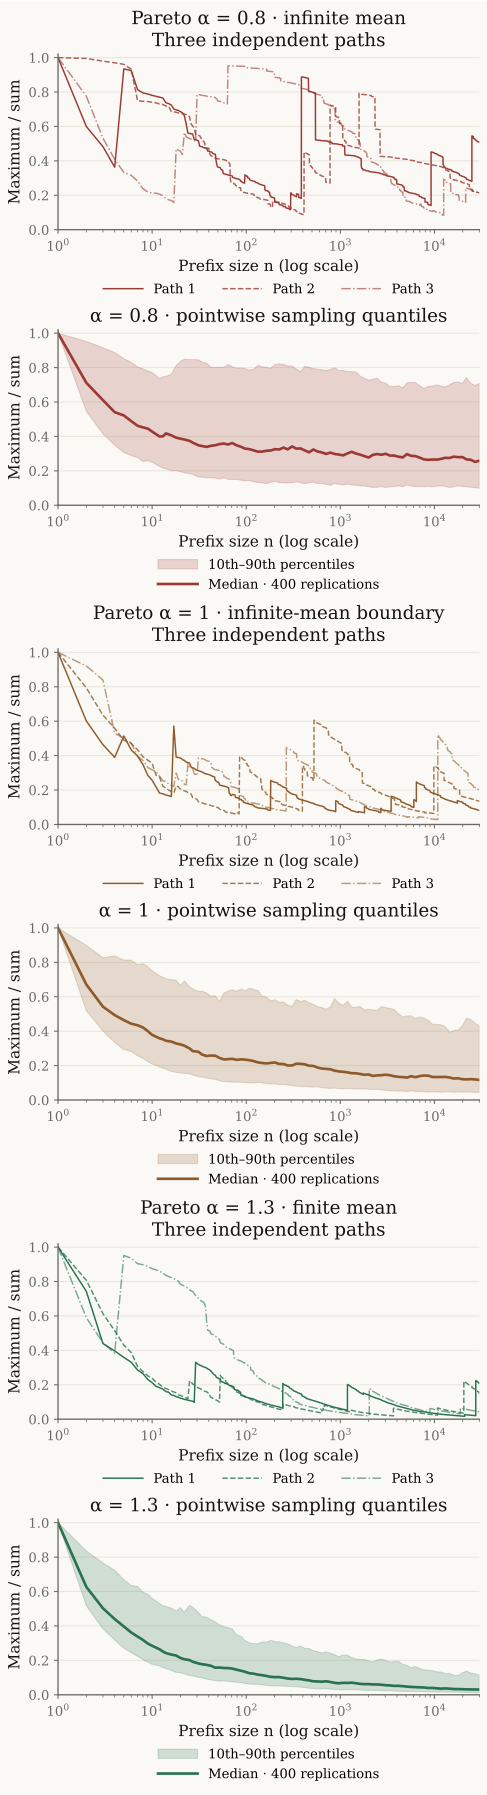
Exact iid Pareto draws with and . Each path panel retains all prefixes for three independent paths. Each companion panel shows pointwise 10th and 90th sampling percentiles and the median from 400 independent paths, evaluated at 100 requested log-spaced checkpoints (duplicate integer checkpoints removed). These are sampling quantiles under specified laws, not confidence intervals or simultaneous path bands. Independent PCG64 streams use seeds 20261030–20261032 for the displayed paths and 20261040–20261042 for the ensembles. The broad shares at do not imply convergence to one; the slow decay at is compatible with an infinite mean and convergence of the ratio to zero in probability. Finite plots do not prove these asymptotic statements.
max_to_sum_path returns
one ratio per prefix. Zero-total prefixes are undefined and return nan.
from xmath.incerto.estimators import max_to_sum_path

path = max_to_sum_path([1, 1, 1, 1, 16, 1, 1, 1, 1])
for n in (4, 5, 9):
    print(f"n={n:d}: ratio={path[n-1]:.4g}")
print("Zero prefix: [" + ", ".join(f"{v:.4g}" for v in max_to_sum_path([0, 2, 2])) + "]")
Output
n=4: ratio=0.25
n=5: ratio=0.8
n=9: ratio=0.6667
Zero prefix: [nan, 1, 0.5]
Regenerate the figure with uv run python demos/incerto/max_to_sum.py.
Reference distributions for the diagnostic¶
Use model-based simulation as the primary reference: specify or fit an iid parent distribution on nonnegative values, simulate independent samples of the observed size , and compute for each sample. Compare the observed with that simulated distribution. Report the parent model, fitted parameters (including for a Pareto model), sample size, simulation count, and seed. The reference assumes the stated parent law is appropriate; a fitted-model comparison is conditional on the fit and needs a separate assessment of parameter uncertainty before it is used as a calibrated test. A tail-only fit also needs a model for the body when includes all observations. A tail exponent alone does not determine a finite- reference. If the model permits zero totals, state whether the reference is conditional on .
As a complement, use -out-of- subsampling without replacement, with and : compute the ratio on all size- subsets, or approximate that distribution using many uniformly sampled subsets. Validity requires a limiting law for the statistic with the normalization appropriate to the parent tail. For example, for a stated exact Pareto exponent, the preceding maximum and sum limits give the following local normalizing factors for :
| Parent regime | |
|---|---|
| 1 |
The Pareto note proves the boundary normalizations and cites the nondegenerate infinite-mean limit. Compare with the subsample values , using the same model parameters. Raw -sample quantiles are not -sample quantiles when . For a general regularly varying parent, slowly varying factors can change the normalization. If its parameters are estimated, justify that their substitution leaves the normalized limit unchanged; mere consistency of an exponent estimate need not control a power of .
For iid data, a nondegenerate weak limit of the normalized statistic and justify convergence of the subsampling distribution at continuity points of the limiting CDF. Estimated centering or normalization must have negligible effect at the subsample scale. We cite this result from Politis & Romano (1994); Bickel, Götze, and van Zwet (1997), Theorem 1, p. 9 gives a proof and an explicit plug-in condition. These are asymptotic conditions; report the chosen and sensitivity to it.
Ordinary -out-of- empirical bootstrap validity is not assumed here. Its maximum cannot exceed the observed maximum, and with a unique sample maximum it equals that maximum with conditional probability . This can obstruct a continuous extreme-value limit. Heavy-tailed sums can also have non-Gaussian stable limits for which ordinary bootstrap approximations fail; see Bickel, Götze, and van Zwet (1997), §2.3, Example 4, p. 5. The finite-mean theorem for proves no resampling validity statement.
Caveats¶
is a dominance diagnostic, not an estimator of the tail exponent.
A small does not prove thin tails. A sample may simply not have seen a record-sized observation yet.
A large can also come from data errors, censoring, mixtures, dependence, or nonstationarity. Inspect the observation before interpreting the ratio as a tail fact.
has no universal “large” threshold. Compare an observed value with a reference distribution under the model and calibration assumptions above.
For signed returns, may be unstable or meaningless because of cancellation. Apply it to nonnegative losses, severities, exposures, or possibly , explicitly changing the interpretation.
A running max-to-sum curve is order-dependent, while the final is not.
For , exact limiting behavior of belongs to stable and Poisson point process asymptotics. Here those limits are cited from Darling (1952) and Resnick (2007); only the finite-mean implication is proved.
References¶
Darling, “The influence of the maximum term in the addition of independent random variables,” Transactions of the American Mathematical Society 73 (1952), 95–107 DOI.
O’Brien, “A limit theorem for sample maxima and heavy branches in Galton–Watson trees,” Journal of Applied Probability 17 (1980), 539–545 DOI.
Politis and Romano, “Large Sample Confidence Regions Based on Subsamples under Minimal Assumptions,” The Annals of Statistics 22 (1994), 2031–2050 DOI.
Bickel, Götze, and van Zwet, “Resampling Fewer than Observations: Gains, Losses, and Remedies for Losses,” Statistica Sinica 7 (1997), 1–31; §2.3, Example 4, and §3, Theorem 1 PDF.
Embrechts, Klueppelberg, and Mikosch, Modelling Extremal Events 1997.
Resnick, Heavy-Tail Phenomena 2007.
Backlinks¶
Depends on: Pareto Distribution, LLN Failure Under Infinite Mean, Pre-Asymptotic LLN Behavior, and the shared sum notation in Shared notation.
Related: Subexponentiality.
Used by: finite-sample tail-risk examples (planned).
- Darling, D. A. (1952). The Influence of the Maximum Term in the Addition of Independent Random Variables. Transactions of the American Mathematical Society, 73(1), 95–107. 10.1090/S0002-9947-1952-0048726-0
- O’Brien, G. L. (1980). A Limit Theorem for Sample Maxima and Heavy Branches in Galton–Watson Trees. Journal of Applied Probability, 17(2), 539–545. 10.2307/3213043
- Politis, D. N., & Romano, J. P. (1994). Large Sample Confidence Regions Based on Subsamples under Minimal Assumptions. The Annals of Statistics, 22(4), 2031–2050. 10.1214/aos/1176325770
- Embrechts, P., Klüppelberg, C., & Mikosch, T. (1997). Modelling Extremal Events. Springer. 10.1007/978-3-642-33483-2
- Resnick, S. I. (2007). Heavy-Tail Phenomena: Probabilistic and Statistical Modeling. Springer. 10.1007/978-0-387-45024-7