Statement¶
We use the symmetric shifted convention defined below; the name “double Pareto” is overloaded in the literature and can also refer to positive-valued size distributions with different left and right exponents. Let have a Pareto Type I distribution with lower cutoff 1 and tail exponent . Let be independent of with . The shifted symmetric double Pareto variable is
Its density on the real line is
The CDF is
For , each one-sided tail has probability
Consequently,
More generally, a location-scale version with has density
The ordinary mean exists and equals 0 exactly when . For , the positive and negative parts are both infinite, so symmetry gives a center but not an ordinary expectation. The variance is finite exactly when , in which case
The absolute moments unify these thresholds:
Here and denote the CDF and density; is an independent sign. denotes the gamma function. Absolute moments diverge for ; the displayed gamma expression only applies for .
Shape and two-sided tail intuition¶
The ordinary Pareto distribution is one-sided: the rare extreme is always on the right. The double Pareto keeps the same power-law magnitude but gives the shock a sign. This makes it useful for toy return models where both large gains and large losses are possible, while preserving a transparent tail exponent.
The density is symmetric, with peak and
Smaller lowers the central density and puts more probability far from zero on both sides. The chance of a large positive value and the chance of an equally large negative value decay at the same power rate.
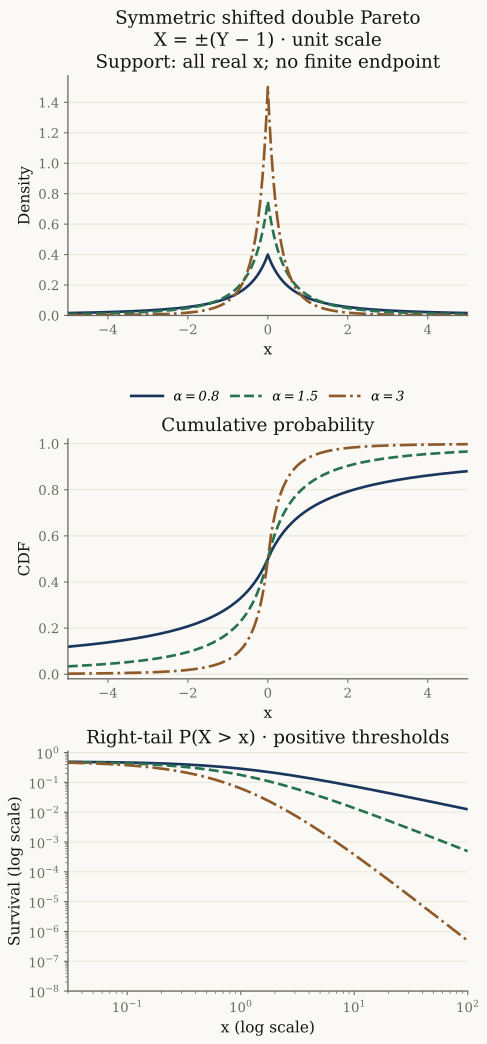
Figure 1:The page’s shifted symmetric law , with unit Pareto minimum and . Support is the whole real line, so there is no finite support endpoint. The log-log panel shows the right-tail probability for ; the absolute-tail probability would be twice as large. The shift causes curvature at small thresholds. No means or variances are matched.
Regenerate the card with uv run python demos/incerto/distribution_cards.py;
the double_pareto example below
uses the same distribution convention.
Derivation from signed Pareto magnitude¶
We derive the symmetric shifted construction used here from the signed Pareto magnitude . The tail, density, and CDF formulas follow directly from symmetry. The moment thresholds use the same Pareto moment logic as Pareto Moment Existence.
For ,
The negative tail is identical by symmetry. Differentiating the CDF on either side gives the density. The expectation is zero only when the first absolute moment exists. When , , so the ordinary mean is undefined even though the distribution is symmetric. Since ,
for . For , the mean exists but the variance is infinite. For , the ordinary mean, and hence variance about that mean, is undefined; the second raw moment is still infinite.
Use double_pareto.
from xmath.incerto.distributions import double_pareto

for alpha in (0.5, 1, 1.5, 2, 3):
    mean, variance = double_pareto(alpha).stats(moments="mv")
    print(f"alpha={alpha:.4g}: mean={mean:.4g}, variance={variance:.4g}")
Output
alpha=0.5: mean=nan, variance=inf
alpha=1: mean=nan, variance=inf
alpha=1.5: mean=0, variance=inf
alpha=2: mean=0, variance=inf
alpha=3: mean=0, variance=1
For , inf reflects the infinite raw second moment,
not variance about an undefined mean.
More generally, integration of the absolute-value density gives the beta integral
Two-sided tail calculations¶
The exact two-sided survival is regularly varying with index . At , its values at are respectively 1, , and . Each one-sided tail has half of that probability.
For a fixed multiplier ,
The shift means this is a limiting power ratio, rather than the exact threshold scaling of an unshifted Pareto law.
At , direct evaluation gives the following exact values.
| Density | CDF | |
|---|---|---|
| -4 | ||
| 0 | ||
| 4 |
The mean is zero and the variance is . These values are formula evaluations, without simulation or an imported distribution package. For max-to-sum diagnostics, use or another explicitly defined nonnegative quantity; signed sums can cancel.
Matching a Student tail or a variance¶
SCoFT v4 §5.3, p. 101 Taleb, 2025, compares a symmetric shifted power law with a Student law. We keep the normalized density above on each side and derive both matching scales. Equal exponents do not imply equal moments or equal leading tail constants.
Let have the unit-scale Student density, with , and let , . Its right tail satisfies
We prove the constant from the density. Factoring out of in the Student density gives . For each , this density lies between times its leading power beyond a fixed threshold. Integrating those bounds from to infinity and letting gives the displayed survival asymptotic. For positive orders , the same comparison proves exactly when ; the density is bounded near zero.
The double-Pareto right-tail constant is at scale one. Matching it requires
For , the Student variance is (the beta-integral moment calculation is also given in the mixture note). Equating that to instead gives
At , . Variance matching uses and gives Student right-tail constant , versus for double Pareto. Their asymptotic survival ratio is even though both variances are one. Tail matching uses and gives Student variance about 1.770683, versus one for double Pareto. Matching tails thus leaves a substantial variance difference in this example.
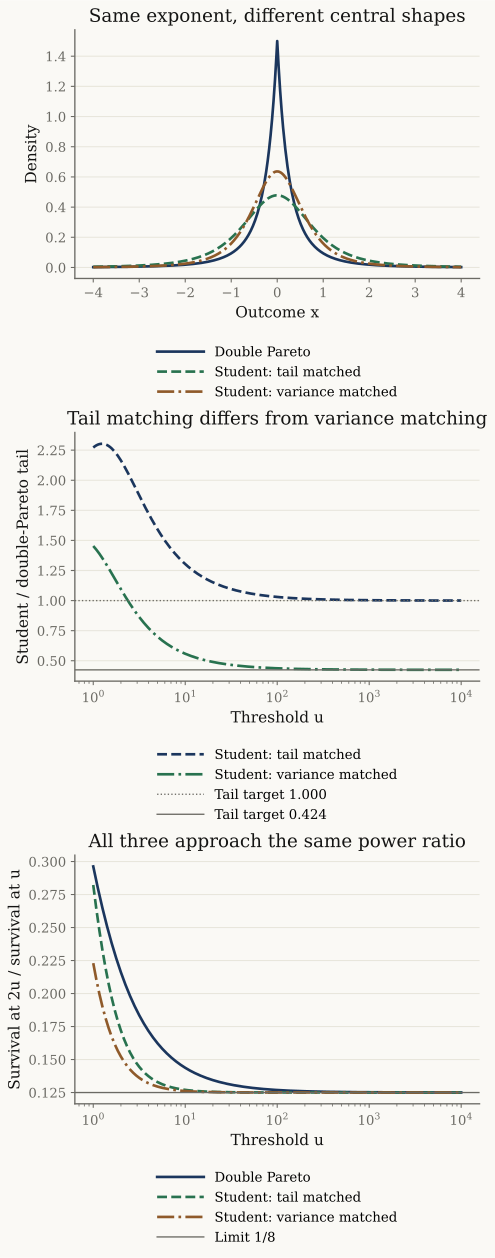
Exact model curves at exponent 3. Top: densities near the center, including the double-Pareto spike at zero; the legend is below the axes so it covers no density curve. Middle: Student survival divided by the double-Pareto survival, with the two asymptotic targets marked. Bottom: multiplier ratios at multiplier 2, approaching . Matching variance and matching a tail constant choose different Student scales; neither makes the distributions identical.
Use double_pareto, student_double_pareto_scales.
from xmath.incerto.distributions import double_pareto
from xmath.incerto.power_laws import student_double_pareto_scales

law = double_pareto(3)
mean, variance = law.stats(moments="mv")
print(f"Mean: {mean:.4g}; variance: {variance:.4g}")
print("Survival at 1, 10: [" + ", ".join(f"{v:.3e}" for v in law.sf([1, 10])) + "]")
print("Student matching:")
for name, value in student_double_pareto_scales(3).items():
    print(f"  {name}: {value:.4g}")
Output
Mean: 0; variance: 1
Survival at 1, 10: [6.250e-02, 3.757e-04]
Student matching:
  student_tail_constant: 1.103
  tail_scale: 0.7683
  variance_scale: 0.5774
  tail_matched_variance: 1.771
Figure regeneration: uv run python demos/incerto/power_laws.py. The figure uses 501 density
points on and 241 thresholds from 1 to 104 for each tail
panel. All values are dimensionless, exact-model evaluations.
Caveats¶
We describe a symmetric signed construction whose magnitude has a Lomax law, not every distribution called “double Pareto” in the literature.
For , even the absolute first moment is infinite. Symmetry can make a formal location or principal-value calculation look harmless while the ordinary expectation is undefined and absolute exposure remains uncontrolled.
The distribution is a pedagogical model. Empirical returns usually need skew, truncation, volatility clustering, dependence, or threshold modeling before a tail fit is credible.
References¶
Taleb (2025), §5.3, p. 101: comparison context. The normalization, tail constants and matching formulas above are derived for our explicit convention.
Resnick, Heavy-Tail Phenomena 2007.
Backlinks¶
Depends on: Pareto Distribution and Regular Variation.
Used by: Chapter 5 and its Student comparison.
- Taleb, N. N. (2025). Statistical Consequences of Fat Tails (3rd ed.). https://arxiv.org/abs/2001.10488v4
- Resnick, S. I. (2007). Heavy-Tail Phenomena: Probabilistic and Statistical Modeling. Springer. 10.1007/978-0-387-45024-7